

10 Essential Data Engineer Skills to Master in 2026: A Complete Learning Guide
Table of content
- At a Glance: 10 Data Engineer Skills (2026)
- Who is a Data Engineer and What Do They Do?
- How Data Engineers Deliver Value to Organizations
- <span style="font-weight: 400;">What Qualifications and Skills Do Data Engineers Need?</span>
- 10 Essential Skills for a Data Engineer
- How to Improve Your Data Engineering Skills: A 2026 Learning Path
- Conclusion
- FAQ
At a Glance: 10 Data Engineer Skills (2026)
| S No. | Skill | Core Tools | Difficulty Level |
| 1 | Programming Languages | Python, SQL, Java | Beginner–Intermediate |
| 2 | Data Warehousing | Redshift, BigQuery, Snowflake | Intermediate |
| 3 | Data Pipelines / ETL | Airflow, Kafka, Azure Data Factory (ADF) | Intermediate |
| 4 | Big Data Technologies | Spark, Hadoop, Hive | Advanced |
| 5 | Cloud Computing | AWS, Azure, GCP | Intermediate–Advanced |
| 6 | Data Modelling | SQL, MongoDB, Cassandra | Intermediate |
| 7 | Data Security & Compliance | GDPR, CCPA, Encryption | Intermediate |
| 8 | Data Visualisation | Tableau, Power BI, Looker | Beginner |
| 9 | Problem-Solving & Debugging | Profiling, Logging, Monitoring | Advanced |
| 10 | Communication & Collaboration | Jira, Confluence, Stakeholder Management | All Levels |
Who is a Data Engineer and What Do They Do?
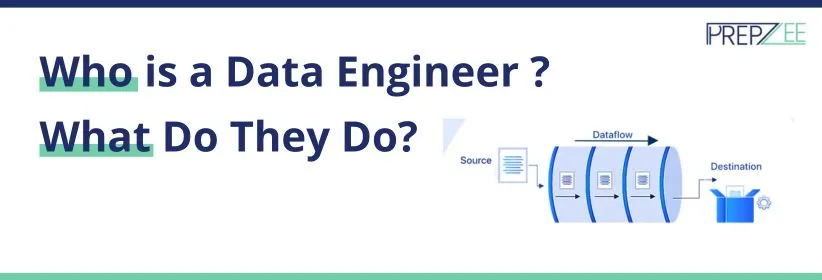
A Data Engineer is an important contributor to creating and managing the infrastructure whereby businesses can store, process, and handle data effectively. Data Engineers collaborate with data analysts and scientists to facilitate seamless data flow for reporting and intelligence.
Understanding the skills required for a data engineer is essential for anyone planning to enter or advance in data engineering. The most important data engineering skills include SQL, Python, data pipelines, cloud computing, data modeling, and big data processing.
Along with these technical skills, data engineers need problem-solving and communication abilities to manage reliable data systems. This guide explains 10 essential data engineer skills for 2026, the tools used in each area, and how beginners and experienced professionals can improve their skills through practical learning.
Their principal responsibilities include designing and optimizing data pipelines, ETL process handling, and database operations such as SQL, NoSQL, and cloud storage solutions. Programming language proficiency in Python, Java, or Scala enables them to automate processes and streamline data processing.
Aside from technical expertise, Data Engineers concentrate on data quality, security, and scalability, ensuring large amounts of data are organized and accessible. Their efforts are crucial in transforming raw information into usable insights that inform business decisions and innovation.
How Data Engineers Deliver Value to Organizations
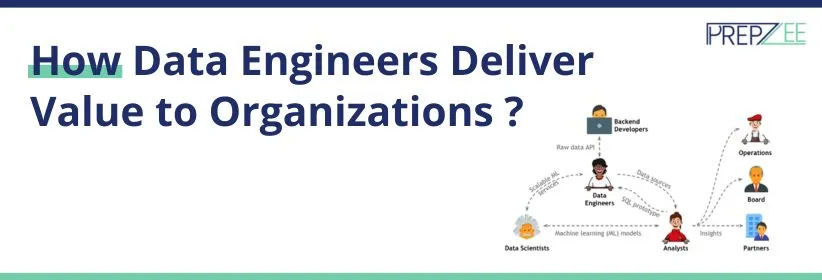
Data Engineers are vital in constructing and supporting the backbone through which organizations can leverage the power of data. They make sure data is gathered, processed, and delivered effectively to facilitate decision-making based on data. Here’s how they deliver value:
● Constructing Data Pipelines : They architect and build data pipelines that elegantly move data from multiple sources to data lakes or warehouses in a stable and unified data environment.
● Guaranteeing Data Quality: By establishing data cleansing and validation processes, they promote accuracy and consistency so that analysts can work with quality data.
● Scalability & Performance: They design systems that are capable of supporting large sets of data, so as the businesses expand, their data infrastructure will be able to scale without any bottlenecks.
● Minimizing Algorithmic Bias: By designing data pipelines with transparency and equity as key considerations, they avoid bias that would affect analytics and machine learning results.
● ETL Processing: They process Extract, Transform, Load (ETL) operations for transforming raw data into structured forms so it can be used for analysis and reporting
● Data Security & Compliance: They use security measures to safeguard sensitive data and keep up with data privacy laws, preserving trust and integrity.
What Qualifications and Skills Do Data Engineers Need?
Data engineering roles require a combination of technical knowledge, practical experience, and problem-solving skills. While some employers prefer relevant degrees or certifications, candidates can also demonstrate their abilities through SQL, Python, cloud projects, and data pipeline experience.
Requirements: A Bachelor’s degree in computer science, engineering, maths, or equivalent IT field is normally preferred given the technical demand of the role. It’s not impossible without a degree but would involve great self-learning efforts and hands-on experience.
Certifications: Obtaining certifications in data engineering frameworks and tools can enhance your resume and highlight your skills. See more: Top Data Engineer Interview Questions and Answers
Experience: The majority of companies prefer candidates with existing experience in data-related positions. Most professionals make a career switch to data engineering from roles such as BI/ETL Developer, QA Testing & Automation, DBA’s, software development, or data analysis after developing relevant skills.
10 Essential Skills for a Data Engineer
In this article, we will explore the top 10 essential skills that every aspiring data engineer needs to master. Whether you’re considering data engineering courses or looking to improve your current skill set, mastering these areas will set you on the path to success.
1. Proficiency in Programming Languages
| Language | Usage & Benefits | Key Technologies |
| Python | Widely used for data manipulation, processing, and automation due to its simplicity and rich libraries. | Pandas, NumPy, PySpark |
| Java | Ideal for building scalable data systems and commonly used in big data frameworks. | Apache Hadoop, Apache Kafka |
| SQL | Essential for querying, managing, and manipulating relational databases. | MySQL, PostgreSQL, SQL Server |
Beginners can improve their programming skills through practical SQL and Python exercises, including database queries, data cleaning, and automated processing tasks.
2. Knowledge of Data Warehousing
Data engineers work with large datasets, and data warehousing is a critical component of this process. Data warehousing involves the storage, management, and retrieval of vast amounts of data in a way that is optimised for analytics. Data engineers must be familiar with various data warehousing technologies such as:
| Tool | Description | Key Features |
| Amazon Redshift | A fully managed data warehouse service that allows fast querying of large datasets. | Scalable, fast queries, integrated with AWS services, columnar storage. |
| Google BigQuery | A fully-managed, serverless data warehouse designed for large-scale data analytics. | Real-time analytics, high scalability, seamless integration with GCP. |
| Snowflake | A cloud-based data warehousing platform that provides scalable data storage and processing. | Multi-cloud, automatic scaling, secure data sharing. |
| Azure Synapse | Microsoft analytics service supporting SQL-based data warehousing and Apache Spark processing. | Dedicated and serverless SQL capabilities, Spark integration, and Azure connectivity. |
These platforms allow data engineers to create efficient data storage solutions that support business intelligence and data analysis. A solid understanding of data warehousing is often covered in data engineer programs, where students learn to manage large data systems effectively.
3. Experience with Data Pipelines
Data pipelines are essential for moving data from one point to another, whether it’s from a data source to a storage solution, or from one database to another. Building reliable and scalable data pipelines is one of the most important technical skills required for data engineering roles. Data engineers should understand how to build both batch and real-time data pipelines. This includes extracting data from different sources, transforming it using SQL or Python, loading it into storage systems, and monitoring workflows for errors. Mastering the following skills is key:
| Tool | Description | Key Use Cases |
| ETL (Extract, Transform, Load) | Fundamental for integrating and processing data from multiple sources. | Designing and implementing data pipelines for efficient data extraction, transformation, and loading into databases or data warehouses. |
| Apache Airflow | Open-source platform for automating workflows and managing tasks. | Scheduling, monitoring, and orchestrating data pipeline processes. |
| Apache Kafka | Distributed event streaming platform for handling real-time data streams. | Real-time data streaming, event-driven architectures, and managing large-scale data ingestion. |
| Azure Data Factory (ADF) | A cloud-based ETL platform that assists in streamlining and automating data work. | Key Use Cases Data integration, pipeline automation, migrating on-prem data to the cloud, data transformation and loading data into Azure services. |
Learners looking for guided practice can review Prepzee’s Data Engineering Job Oriented Program to understand the available training curriculum.
4. Big Data Technologies
Organisations generate massive amounts of data. Big data technologies are essential for storing, processing, and analysing these vast datasets. A data engineer needs to master the following big data tools:
| Tool | Description | Key Use Cases |
| Apache Hadoop | Framework for distributed storage and processing of large datasets across many machines. | Handling large-scale data storage and distributed processing. |
| Apache Spark | In-memory data processing engine capable of handling batch and real-time data. | Real-time data processing, machine learning, and batch processing. |
| Apache Hive | Data warehouse software built on Hadoop, designed for data summarization and querying. | Data analysis, summarization, and querying of large datasets. |
Mastering big data tools is essential for any data engineer looking to work with complex datasets. Hands-on experience with Apache Spark and distributed data processing helps engineers understand how large datasets are managed efficiently.
5. Cloud Computing Expertise
Cloud computing has become an integral part of modern data infrastructure. Data engineers need to be familiar with cloud platforms that allow businesses to store and manage data in scalable and flexible environments. The three major cloud providers are:
| Platform | Description | Key Services |
| Amazon Web Services (AWS) | A comprehensive cloud computing platform offering data engineering services. | S3 (storage), Redshift (data warehousing), AWS Data Engineering Services |
| Microsoft Azure | A cloud platform offering a variety of data management and storage solutions. | Azure SQL Database, Azure Data Lake Storage |
| Google Cloud Platform (GCP) | A cloud service offering powerful tools for data analytics and storage. | BigQuery (data analytics), Cloud Storage (file storage) |
| Microsoft Fabric | Microsoft’s unified analytics platform for data engineering, warehousing, and business intelligence. | OneLake, Data Factory, Lakehouse, Data Warehouse, and Power BI. |
Professionals interested in Microsoft Fabric can explore Microsoft Fabric Data Engineer Training to develop platform-specific data engineering skills.
6. Data Modelling and Database Design
Data modelling is the process of creating a blueprint for how data will be stored and organised within a database. This skill is critical for ensuring that data is structured in a way that is efficient for both storage and retrieval. Data engineers must have a solid understanding of:
| Concept | Description | Key Focus |
| Normalization | Organizing data to reduce redundancy and improve data integrity. | Ensuring data consistency and efficient storage by organizing tables. |
| Schema Design | The process of designing relational database schemas for optimal querying and storage. | Structuring data models to support scalability and efficient querying. |
| NoSQL Databases | Databases designed for handling unstructured or semi-structured data. | Familiarity with databases like MongoDB and Cassandra for flexible, scalable data storage. |
Strong data modeling and database design skills help data engineers create organized, scalable, and efficient data storage systems.
7. Data Security and Compliance
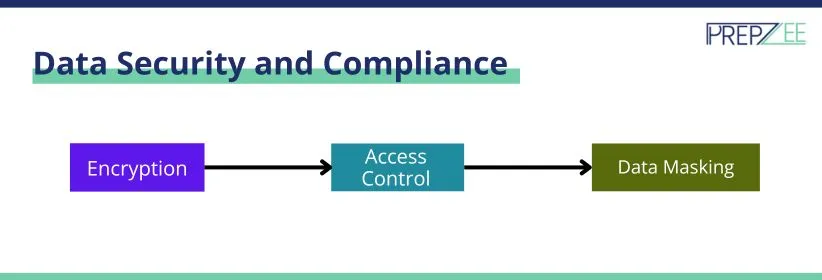
As data privacy laws become more stringent, data engineers need to be well-versed in data security and compliance. Understanding the importance of securing sensitive data is essential for ensuring that organisations comply with regulations such as the GDPR (General Data Protection Regulation) and CCPA (California Consumer Privacy Act). Key aspects of data security for engineers include:
| Concept | Description | Key Focus |
| Encryption | Protecting data by converting it into a secure format during storage and transmission. | Ensuring data confidentiality during storage and while in transit. |
| Access Control | Implementing role-based access controls to limit who can access sensitive data. | Assigning permissions to users based on roles to secure data access. |
| Data Masking | Obscuring sensitive data to prevent unauthorized access while maintaining its usability. | Masking data elements like credit card numbers or personal identifiers for privacy |
Data engineers must be able to design systems that meet security requirements while ensuring that data remains accessible for analysis. Data engineer training and placement programmes often focus on teaching these critical compliance and security skills.
8. Data Visualisation and Reporting
While data engineers are primarily focused on building systems to process and store data, they should also have a basic understanding of data visualisation and reporting. This skill helps engineers collaborate with data scientists and analysts to ensure that the data they manage can be easily understood and used for decision-making. Some tools and technologies to be familiar with include:
| Tool | Description | Key Features |
| Tableau | A powerful data visualization tool that allows users to create interactive dashboards. | Interactive dashboards, easy sharing, and real-time data integration. |
| Power BI | A Microsoft tool used for creating reports and dashboards, with seamless integration into other Microsoft products. | Integration with Microsoft tools, real-time data updates, customizable reports. |
| Looker | A data exploration and visualization platform that enables users to analyze and visualize data in real-time. | Real-time data analysis, collaborative dashboards, integration with SQL databases. |
While data engineers don’t need to be expert visualisers, having a foundational knowledge of these tools helps them work effectively within a team.
9. Problem-Solving and Debugging
Data engineers often work with large, complex systems that can present a variety of technical challenges. Being able to troubleshoot and debug issues effectively is a crucial skill. Data engineers need to be able to:
| Task | Description | Key Focus |
| Identify Performance Bottlenecks | Optimizing data processing or storage systems to improve speed and efficiency. | Analyzing data flow to identify slow points and implementing performance enhancements. |
| Debug Data Pipelines | Troubleshooting and resolving issues that cause data pipeline failures. | Monitoring, tracing, and fixing pipeline breakdowns to ensure continuous data flow. |
| Handle Data Inconsistencies | Addressing issues like corrupted, missing, or inconsistent data. | Developing strategies for data validation, cleaning, and recovery to ensure data integrity. |
Problem-solving and debugging are often covered in data engineer program curricula, where students can practise solving real-world challenges.
10. Collaboration and Communication
While technical skills are crucial, a data engineer also needs to work closely with other teams, including data scientists, analysts, and business leaders. Strong communication skills are essential for translating complex technical concepts into simple explanations for non-technical stakeholders. Moreover, collaboration skills are important when working on large projects that involve multiple departments.
Many data engineer courses with placement provide opportunities for students to work in teams, enhancing their communication and collaboration abilities, which are vital for career success.
How to Improve Your Data Engineering Skills: A 2026 Learning Path
Building a successful career in data engineering requires a structured approach. Rather than trying to learn everything at once, focus on mastering the right skills at each stage of your journey.
Beginner (0–6 Months)
Start by building a strong foundation in SQL and Python, as these are the core languages used by data engineers. Learn database fundamentals and choose one cloud platform-preferably AWS or Azure-to understand storage, compute, and basic data services. Hands-on practice with small projects will help reinforce these concepts.
Intermediate (6–18 Months)
Once you are comfortable with the basics, begin creating real-world data pipelines using tools like Apache Airflow and explore distributed data processing with Apache Spark. Gain practical experience with cloud-native data services and explore certifications relevant to your preferred platform, such as AWS Certified Data Engineer – Associate or Microsoft Fabric Data Engineer Associate (DP-700).
Advanced (18+ Months)
At the advanced level, focus on mastering distributed systems, data architecture, and performance optimization. Contribute to open-source projects, work with streaming technologies, and deepen your understanding of scalability and reliability. Pursuing architect-level certifications and staying current with modern data platforms can help you move into senior or leadership roles.
For AWS-focused learning, explore AWS Data Engineering Training and its practical curriculum.
Start Your Data Engineering Journey with Prepzee
Prepzee’s Data Engineering courses are structured around this exact learning path, combining hands-on projects, industry-relevant tools, and certification preparation to help you progress from beginner to advanced data engineer with confidence.
Conclusion
Developing strong data engineer skills requires practical experience with SQL, Python, data pipelines, cloud platforms, and database technologies. Beginners should start with programming and data fundamentals, while experienced professionals can focus on big data processing, orchestration, and cloud architecture.
Consistent hands-on practice is essential for strengthening data engineering technical skills and preparing for real-world responsibilities.
Prepzee offers structured data engineering training designed around practical exercises, relevant technologies, and career preparation.
Explore Data Engineering Training
FAQ
The most prominent trends are the emergence of serverless data processing, real-time data pipelines, AI and ML integration into workflows, and data mesh architecture for improved scalability and accessibility.
They create and manage data pipelines, maintain data quality, and optimize storage, allowing data scientists to work with clean, structured data for reliable machine learning models.
Yes, SQL is a fundamental skill for querying and managing databases. It assists data engineers in efficiently transforming, manipulating, and maintaining data in their pipelines.
Python, SQL, Java, and Scala are most widely used in data engineering for data manipulation, automation, and big data processing.
Some of the most popular ones are Apache Spark, Hadoop, Airflow, Kafka, Snowflake, Redshift, BigQuery, and cloud infrastructure such as AWS, Azure, Microsoft Fabric and Google Cloud.
Data engineering course concentrates on developing and managing data infrastructure, whereas data science course entails digging into and inferring insights out of that data with the aid of statistical models and machine learning.
Cloud platforms offer scalable storage, compute resources, and managed data processing services at a lower cost, increasing efficiency.
Data engineers are employed in most industries, such as finance, healthcare, e-commerce, technology, and telecom.
Acquiring experience in adjacent disciplines such as software development, database administration, or data analysis and learning corresponding tools and technologies may facilitate the move into a data engineering position.
Improving your data engineering skills requires a structured approach and consistent hands-on practice. Start by strengthening your SQL and Python fundamentals, as they form the backbone of most data engineering workflows. Next, gain experience with ETL tools, data modeling, and cloud platforms such as AWS or Azure.
As you progress, build real-world data pipelines using tools like Apache Airflow, Spark, and Kafka, and work with modern data warehouses such as Snowflake or BigQuery. Earning industry certifications, contributing to open-source projects, and staying updated with emerging technologies can further accelerate your growth. Following a clear learning path and regularly applying new concepts to practical projects is the most effective way to become a more skilled data engineer.
If you’re already working, focus on continuous learning through hands-on projects, cloud certifications, and exposure to modern tools such as Apache Airflow, Spark, and Kafka. Contributing to open-source projects, practicing with real-world datasets, and following a structured learning path can help you deepen your expertise and stay competitive in the evolving data engineering landscape.
To become a data engineer, you need a combination of technical and soft skills. The most important skills include SQL, Python, data modeling, ETL pipelines, cloud platforms such as AWS or Azure, big data technologies like Spark, and problem-solving abilities. Communication and collaboration skills are also essential when working with cross-functional teams.
The learning timeline depends on your background and goals. Beginners can acquire foundational skills in SQL, Python, and cloud computing within 3–6 months. Becoming job-ready typically takes 6–12 months of consistent learning and hands-on practice, while mastering advanced topics such as distributed systems and architecture may take 18 months or longer.
SQL should be your first priority because it is the foundation of data engineering. After that, Python is the most recommended programming language due to its extensive ecosystem for data processing and automation. Learning Java or Scala can be beneficial for working with big data frameworks like Apache Spark.
Python is one of the most important languages for data engineering, but it is not enough on its own. Data engineers also need strong SQL skills, knowledge of databases, cloud platforms, ETL tools, and big data technologies. Combining Python with these technologies creates a more complete skill set for modern data engineering roles.
Data engineers focus on building and maintaining data pipelines, storage systems, and infrastructure that enable data processing. Data scientists, on the other hand, analyze data and develop machine learning models to generate insights. In simple terms, data engineers create the foundation that allows data scientists to work effectively.
Some of the typical challenges are processing large amounts of data, providing data quality, dealing with real-time processing, performance optimization, and security and compliance.
Siddharth Sharma


