


SQL for Data Engineering: Skills & Topics You Need to Master in 2026
Table of content
- Why Is SQL Essential for Data Engineering?
- SQL for Data Engineering: What Should You Learn First?
- 1. Master SQL Fundamentals and Joins
- 2. Learn CTEs, Subqueries, and Window Functions
- 3. Understand Data Modeling and Database Design
- 4. Learn Data Quality, NULL Handling, and Duplicate Detection
- 5. Learn Incremental Loading and SQL Transformations
- 6. Master SQL Query Optimization
- 7. Understand Transactions and ACID Properties
- Which SQL Interview Questions Should You Practice?
- Build One Practical SQL Data Engineering Project
- Final Takeaway
- FAQ
SQL is one of the most important skills for Data Engineers, but knowing how to write SELECT statements is only the beginning.
In real data engineering projects, SQL is used to transform raw information, build data warehouse tables, identify inconsistencies, optimize queries, and maintain reliable data pipelines.
So, how much SQL do you actually need to learn?
The goal is to move beyond writing queries and understand how to use SQL to build efficient, accurate, and maintainable data systems.
This guide covers the essential SQL topics, advanced techniques, interview questions, and practical skills you should prioritize in 2026.
Why Is SQL Essential for Data Engineering?
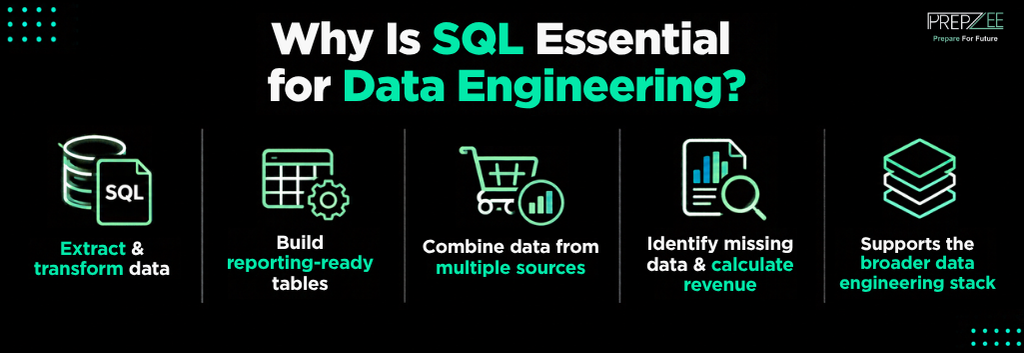
Data Engineers use SQL throughout the data lifecycle, from extracting records and transforming datasets to building reporting-ready tables.
Consider an e-commerce company collecting information from its sales, inventory, and customer databases.
SQL helps engineers combine these datasets, identify missing transactions, calculate revenue, and create tables that downstream applications can use.
However, SQL is only one component of the broader engineering stack. Python, cloud platforms, orchestration, and data modeling also play important roles.
For a complete overview of these technologies, explore Prepzee’s Data Engineer Roadmap for 2026.
SQL for Data Engineering: What Should You Learn First?
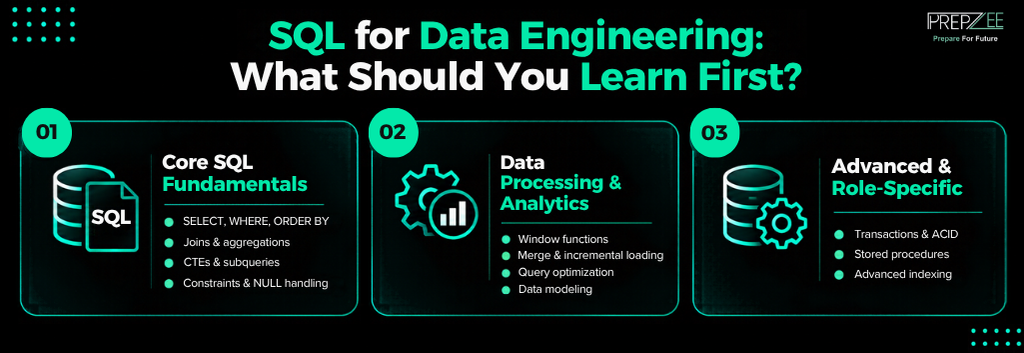
Not every SQL topic requires the same level of attention. Prioritize the skills you will use when developing and maintaining data pipelines.
| SQL Topic | Priority | Practical Application |
| SELECT, WHERE, ORDER BY | Essential | Retrieve and filter data |
| Joins and aggregations | Essential | Combine and summarize datasets |
| CTEs and subqueries | Essential | Organize complex transformations |
| Window functions | High | Ranking, deduplication, and trends |
| Data modeling | High | Design warehouse tables |
| Constraints and NULL handling | Essential | Maintain data integrity |
| MERGE and incremental loading | High | Process changing records |
| Query optimization | High | Improve performance |
| Transactions and ACID | Intermediate | Maintain consistency |
| Stored procedures and advanced indexing | Role-dependent | Database-specific workflows |
Start with fundamentals, then apply advanced concepts through practical data engineering scenarios.
1. Master SQL Fundamentals and Joins
Begin with SELECT, WHERE, GROUP BY, HAVING, ORDER BY, and aggregate functions such as COUNT, SUM, AVG, MIN, and MAX.
Then focus on joins.
- INNER JOIN: Returns matching records from both tables.
- LEFT JOIN: Preserves all records from the left table and adds matching data from the right.
- FULL OUTER JOIN: Preserves records from both tables, including unmatched rows, where supported.
- CROSS JOIN: Produces combinations of rows from two tables.
Understanding joins is essential, but you should also understand their impact on data accuracy.
Practical example: You need to combine orders with customer information. If the customer table contains duplicate customer IDs, the join may multiply order records and inflate reported revenue.
Always verify your join keys and expected row counts.
Also understand the difference between WHERE and HAVING. WHERE filters individual rows, while HAVING filters grouped results.
2. Learn CTEs, Subqueries, and Window Functions
Complex SQL transformations become easier to understand when divided into smaller logical steps.
Common Table Expressions (CTEs) help organize intermediate query results. Subqueries allow you to use the output of one query inside another.
Window functions are particularly valuable for Data Engineering because they perform calculations across related rows without necessarily collapsing the result into one row per group.
Focus on:
- ROW_NUMBER for assigning sequential row numbers.
- RANK and DENSE_RANK for ranking records.
- LAG and LEAD for comparing previous or subsequent rows.
- SUM with OVER for cumulative calculations.
Practical example: A customer table receives multiple updates for the same customer. You can use ROW_NUMBER, partitioned by customer ID and ordered by update time, to identify the latest record.
Include a stable tie-breaker when timestamps are identical to avoid unpredictable results.
These techniques are useful for deduplication, incremental transformations, historical comparisons, and reporting datasets.
3. Understand Data Modeling and Database Design
Writing correct queries is important, but Data Engineers must also understand how data should be structured.
Start with primary keys, foreign keys, normalization, and relational database design.
Then learn analytical modeling.
| Data Model | Structure | Typical Use |
| Star schema | Fact table connected to denormalized dimensions | Reporting and analytics |
| Snowflake schema | Fact table connected to normalized dimensions | Complex dimension relationships |
| Third Normal Form (3NF) | Tables organized to reduce redundancy and update anomalies | Operational data systems |
A star schema might contain a sales fact table connected to customer, product, and date dimensions.
Before designing the table, establish its grain: what one row represents.
For example, a sales fact table might contain one row per order item rather than one row per order.
This distinction affects joins, aggregations, and reporting accuracy.
4. Learn Data Quality, NULL Handling, and Duplicate Detection
Production SQL must protect data quality, not simply return results.
Understand constraints such as PRIMARY KEY, FOREIGN KEY, UNIQUE, NOT NULL, and CHECK.
Also learn how NULL behaves in comparisons, joins, and calculations.
For example, a missing payment amount should not automatically be treated as zero because the two values have different business meanings.
Practice identifying duplicate records using GROUP BY and HAVING, then learn how window functions can identify which record should be retained.
Practical goal: Build SQL validation checks for missing IDs, duplicate transactions, invalid amounts, and unmatched customer records.
These checks should follow documented business rules rather than assumptions.
5. Learn Incremental Loading and SQL Transformations
One major difference between analytical SQL and production data engineering is how frequently queries must run.
A reporting query may execute occasionally. A transformation pipeline might process new records every hour or every day.
Learn the difference between full refreshes and incremental loading.
Understand INSERT, UPDATE, DELETE, and MERGE or equivalent upsert functionality.
For example, when new sales records arrive, an incremental pipeline should process the required changes without unnecessarily rebuilding the entire dataset.
You should also understand idempotency: rerunning a pipeline should not introduce duplicate records or incorrect totals.
For deeper learning about cloud-based transformations, explore Prepzee’s DP-700 Microsoft Fabric Certification Guide .
6. Master SQL Query Optimization
A query can produce correct results and still be unsuitable for production if it consumes excessive resources.
Learn to investigate slow queries using execution plans.
For example, PostgreSQL’s EXPLAIN documentation describes how execution plans reveal table scans, index usage, and join strategies.
Important optimization techniques include:
- Selecting only required columns.
- Filtering unnecessary records early where appropriate.
- Understanding indexes and partitioning.
- Avoiding unnecessary joins and repeated calculations.
- Checking execution plans and database statistics.
Performance depends on the database engine. Traditional relational database indexing strategies may differ from optimization techniques used by cloud warehouses such as BigQuery or Snowflake.
Always measure the actual workload before deciding which optimization to apply.
7. Understand Transactions and ACID Properties
Data Engineers should understand how databases preserve consistency when multiple operations occur.
ACID stands for Atomicity, Consistency, Isolation, and Durability.
For example, a financial transfer involving two account updates should not leave the system in an inconsistent state if one operation fails.
Also understand transaction isolation and common concurrency problems such as dirty reads, lost updates, and deadlocks.
These concepts become especially relevant when working with operational databases, concurrent data loads, or systems that require transactional guarantees.
Which SQL Interview Questions Should You Practice?
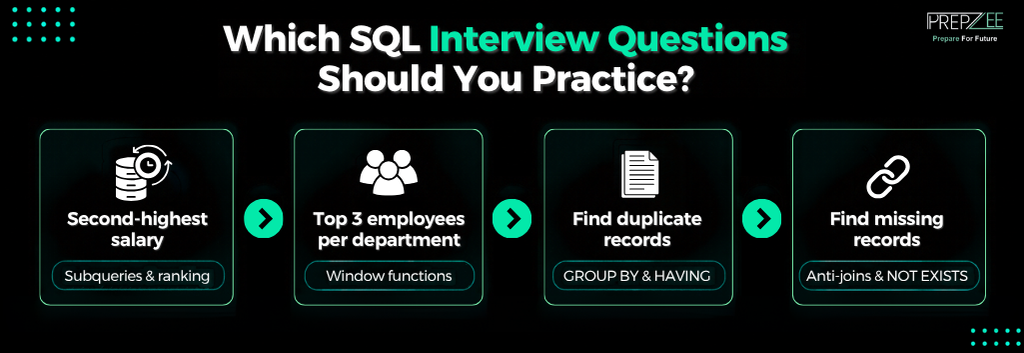
Interview preparation should combine query-writing exercises with explanations of real engineering problems.
| Interview Question | Skill Tested |
| Find the second-highest salary | Subqueries and ranking |
| Find the top three employees per department | Window functions |
| Identify duplicate records | GROUP BY and HAVING |
| Find records missing from another table | Anti-joins and NOT EXISTS |
| Calculate running sales totals | Window aggregations |
| Find the latest customer record | ROW_NUMBER and ordering |
| Explain DELETE vs TRUNCATE | Data manipulation and database behavior |
| Optimize a slow SQL query | Execution plans and performance |
When practicing, explain your reasoning instead of memorizing one solution.
For example, when removing duplicates, clarify which columns define uniqueness and which record should be retained.
For additional practice, read Prepzee’s Data Engineer Interview Questions and Answers .
Build One Practical SQL Data Engineering Project
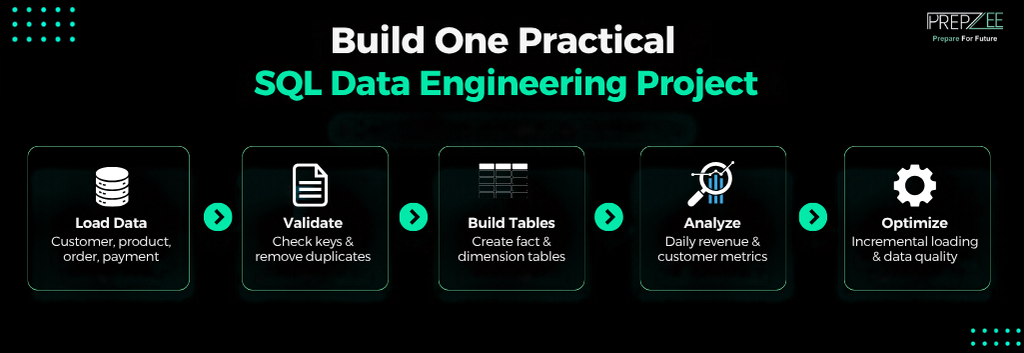
Project: E-Commerce Sales Data Warehouse
Create a small data warehouse using customer, product, order, and payment datasets.
Your project should:
- Load raw records into staging tables.
- Validate primary keys and identify duplicates.
- Join related datasets.
- Build sales fact and dimension tables.
- Calculate daily revenue and customer metrics.
- Implement incremental loading.
- Test data quality and optimize slow queries.
Document the table grain, transformation logic, validation checks, and performance improvements.
This project demonstrates SQL skills across the full data engineering workflow rather than isolated interview exercises.
For structured training involving SQL, Azure, Fabric, Databricks, and production pipelines, explore Prepzee’s Data Engineering Job-Oriented Program .
Final Takeaway
Mastering SQL for Data Engineering means moving beyond basic queries.
Start with joins and aggregations, then develop skills in CTEs, window functions, data modeling, incremental loading, and query optimization.
Most importantly, apply these concepts to realistic datasets and build a project that demonstrates data quality, performance, and reliable transformations.
The goal is not simply to write SQL that works. It is to create SQL-based data systems that remain accurate, efficient, and maintainable.
Frequently Asked Questions
FAQ
You should be comfortable with joins, aggregations, CTEs, window functions, data modeling, NULL handling, query optimization, and practical transformation workflows.
Advanced SQL is useful for complex transformations, deduplication, incremental processing, and performance optimization. Start with fundamentals before moving to these concepts.
Both are important. SQL handles database queries and transformations, while Python supports automation, API integration, and custom processing.
Yes. Window functions are useful for ranking records, identifying the latest entries, calculating running totals, and comparing historical values.
PostgreSQL is a practical starting point for relational SQL fundamentals. You can later learn the SQL dialect used by your target employer, such as SQL Server, Snowflake, or BigQuery.
No. SQL is foundational, but Data Engineers also need knowledge of Python, databases, data modeling, pipelines, cloud platforms, and reliability.
Siddharth Sharma